
Checking neuron steering with Off, zero and signed doses
Neuron steering changes selected activations during inference while keeping checkpoint weights frozen. We ran a small CUDA check on Qwen3-8B to verify the intervention, its controls and the saved profile before measuring answer quality.
The prompt was: Complete the sentence: The capital of France is. We used two MLP coordinates, layer 14 neuron 8949 and layer 13 neuron 7956, with doses scaled by the original prompt's residual calibration. Each variant generated four tokens.
What the controls showed
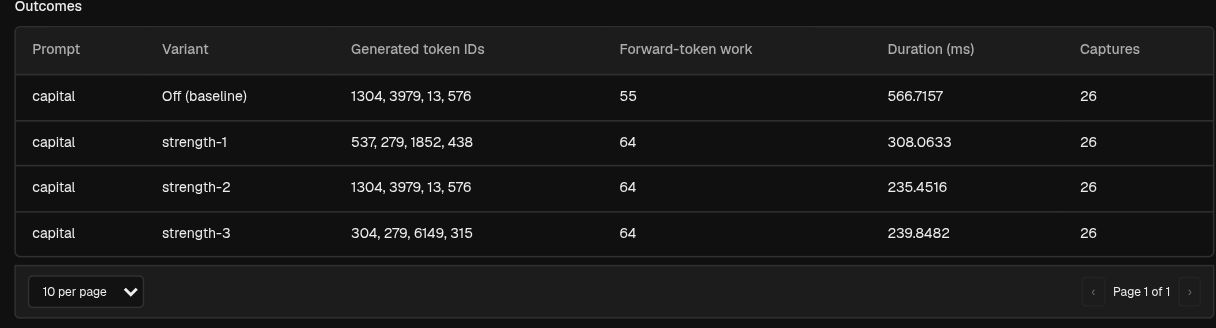
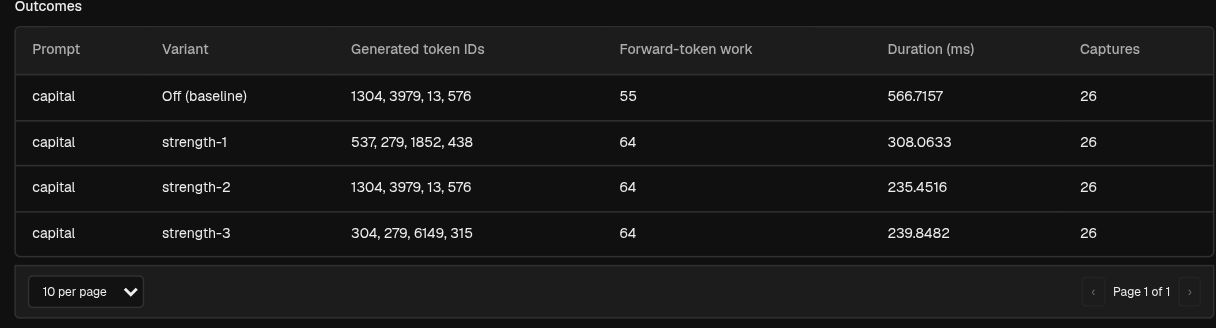
Four variants from the same native execution: strength-1 reverses the authored signs, strength-2 is zero dose, and strength-3 applies the authored signs. Durations cover individual outcomes, not startup or total runtime. Different tokens do not establish a better answer.
Open the full-size result image.
| Variant | Layer 14 dose | Layer 13 dose | Comparison with Off | Generated token IDs |
|---|---|---|---|---|
| Off | No intervention | No intervention | Reference | 1304, 3979, 13, 576 |
| Enabled zero | 0 | 0 | Identical captures and generated tokens | 1304, 3979, 13, 576 |
| Reversed signs | −1 | +1 | Changed activations and generated tokens | 537, 279, 1852, 438 |
| Authored signs | +1 | −1 | Changed activations and generated tokens | 304, 279, 6149, 315 |
The run retained 104 activation captures, 26 per variant. Off and enabled zero matched exactly across all 26 before/after capture records and the generated token sequence. Each nonzero intervention changed its 26 captured values and produced a different continuation.
Compare captures only while their causal input prefixes match. Once generated tokens diverge, later positions no longer represent the same input context.
Retaining the intervention
We saved the authored-sign profile as one Model version, then independently reopened the exact profile and version through the API. Saving did not launch another run or activate serving.
The settled usage charge was $0.462794, including startup and model work. Post-completion warm idle was not charged to this run. This is an observed charge for this case, not a price guarantee. Physical deletion was confirmed after the trial's cleanup deadline, so cleanup timing remains an open acceptance check.
This check establishes a working intervention, a zero-dose control and retained profile identity. It does not establish answer quality, a reliable personality change, effects on other checkpoints or production serving. Serving still needs an independently qualified exact runtime and billing profile.
For the calibration, token scope and verified SDK/CLI workflow, see the neuron-steering guide.
For background, Steering Language Models With Activation Engineering describes inference-time activation control. Its ActAdd prompt-pair vectors differ from the selected-neuron doses used here; this check does not reproduce its results.