
Training Engram memory on a frozen Qwen model
Engram adds learned token-history memory inside a language model. Our current implementation trains memory tables, projections and gates at four layers of a frozen Qwen3-8B base. It is a different modification from a LoRA adapter.
We ran a small functional check with four reviewed GSM8K demonstrations, four optimizer steps, a learning rate of 0.001 and a 1,024-token sequence limit. The purpose was to verify actual training and retained learned state before measuring answer quality.
What completed
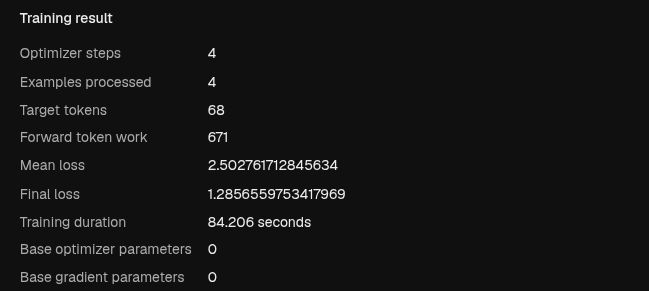
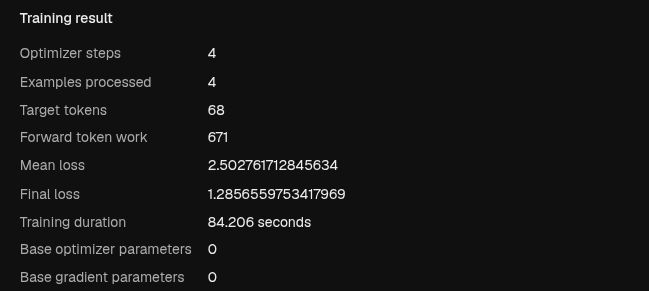
Actual result metrics from the four-step check. Training duration excludes the cold model download and startup.
The trainer processed 68 target tokens in 84.206 seconds. Mean training loss was 2.502762 and final training loss was 1.285656. These are training summaries, not a baseline-versus-candidate evaluation.
The base-weight hashes matched before and after training, and the base had zero optimizer and gradient parameters. Learned memory state changed and was retained in a 1.31 GB tensor file. Before publication, the producer loaded the written artifact into a fresh CPU adapter and verified its state. We then saved one Model version and reopened that exact version through the API and web app.
The settled training charge was $0.883725, including billable startup and model work. The GPU was deleted after completion; warm idle after completion was not charged to this run. This observed charge is specific to this short check.
What comes next
This check establishes training and artifact retention. It does not establish better math answers, held-out quality, production serving or an On/Off inference comparison. Engram serving still requires an independently qualified exact runtime and billing profile. A saved version alone does not supply that proof.
For the architecture, reviewed Dataset setup and verified SDK/CLI workflow, see the Engram adapter guide. The conditional-memory adapter paper and DeepSeek's original Engram repository provide architectural background. This Qwen implementation makes no claim to reproduce their results.