
Log an Issue: Building Continual Learning Datasets From Your AI Agents’ Errors
You notice an agent skipped a requirement, misunderstood a request, or repeated an earlier mistake. You correct it, finish the work, and move on. The useful example often stays buried in that conversation.
We're building Log an issue in OpenPond Desktop to make that moment useful beyond the current chat. Click the button, ask the agent to record what went wrong, and keep the example in a Dataset you can review. Those reviewed examples can become evaluations or data for a model you choose to train.
1. Download Desktop and sign in
Download OpenPond Desktop, create an account or sign in, and select the workspace where you want to keep your examples. Open an existing agent conversation in Desktop so the mistake and the surrounding instructions are available together.
Start with the agent you already use. You don't need to train a model or enable a recurring learning policy before collecting useful examples. An existing conversation still needs a working agent connection to accept the request; opening its history alone does not grant new tools or permissions.
2. Notice a mistake and click Log an issue
The Log an issue button sits beside the context indicator at the bottom of the conversation composer. It sends a short request into the same conversation:
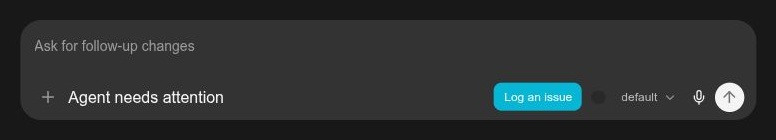
The Log an issue control in the composer UI preview.
Review the latest issue and add a task to my Corrections dataset. Include what went wrong, the expected behavior, and relevant context. After this is done, continue with what you were currently working on.
During an active supported turn, the request uses the existing steering flow. When the conversation is idle, it sends a normal follow-up. Your unsent message and attachments stay in the composer.
The agent handles the recording through its existing OpenPond tools and then continues its previous work. This is a deliberate user action, not a background monitor that uploads every conversation or detects every error.
A sent request is not yet a saved example. Check the agent's response and the actual task in the Dataset before treating capture as complete. Review whether it recorded the right mistake, the behavior you expected, and enough context for a future attempt.
3. Keep the examples in Corrections
The account setup flow we're designing gives each user a private Corrections Dataset, an Instruction following grader configuration, and a linked, untrained Corrections Model. These are account resources, so opening Desktop isn't what creates them. Existing users should receive the same starting point without losing examples they've already saved.
The Model is a place to configure future learning, not a trained model version. It starts without a selected base model or recipe, and without an enabled continual-learning policy. Nothing is training or serving merely because the record exists.
Open Corrections alongside your other Datasets to inspect the examples. Desktop's issue-logging settings let you choose another private, editable Dataset as the destination for future requests. The shared name doesn't mean shared contents: your corrections remain private to you.
You can capture a useful mistake from a GPT or Claude conversation without being able to train GPT or Claude. The source of an example and the model you later train are separate choices. Recording the example does not give OpenPond access to a proprietary model's weights.
4. Review the tasks and graders
Open Corrections and inspect each task. Is the expected behavior clear? Does the context support the claim that something went wrong? Has a proposed fix actually been checked? An error log can be useful evidence without being a verified reference answer.
Instruction following uses OpenPond's LLM-as-judge workflow and starts as an editable grader configuration. Choose a supported judge model and complete the normal validation and calibration setup before relying on its scores.
Logging another issue adds another task. It does not generate a new grader for each issue, run the judge, or start training. You can edit the rubric and add checks suited to the task. A calculation may need an executable verifier; a claim about a repaired application may need evidence from running it.
The Dataset guide and grader guide cover the normal review and setup paths.
5. Choose evaluation or training
A growing Corrections Dataset is useful even before you train anything. Use reviewed tasks to evaluate another attempt or compare compatible models against the same criteria. Keep incomplete examples out of training until they have the instructions and evidence the chosen workflow needs.
When you choose training, open the linked Model, select a compatible base model and recipe, prepare the Dataset and graders, and authorize the run and its budget. SFT needs suitable target examples; RL generates fresh attempts and uses the configured graders to score them. A captured failure alone does not supply everything either workflow needs.
Compare a candidate with the baseline on independent held-out tasks, including work that checks for regressions. Better performance on the examples used for training does not establish a broader improvement. Serving the candidate is a separate decision.
For supported SFT/LoRA and RL/LoRA workflows, you can later configure a continual-learning policy with explicit data, schedule, budget, and candidate-approval settings. Consult the adapter guide when choosing a compatible workflow.
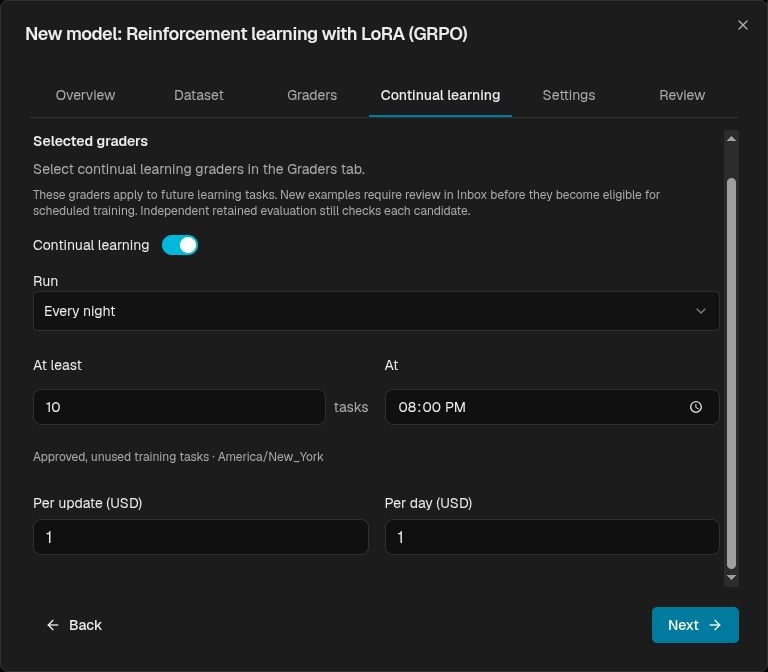
Configure a schedule, minimum batch size and spending limits when you're ready to enable learning. Creating the Corrections Model leaves learning off.
The connection to continual learning begins with a small habit: when an agent makes a mistake worth remembering, record it while the context is fresh. Review what was saved, decide how to measure a better attempt, and choose when those examples should lead to a model update.