
Activation inspection: a prompt and the activations it produces
Activation inspection records selected neuron values as a model processes a prompt and generates tokens. It applies no steering dose and runs no optimizer. We completed a bounded CUDA check on Qwen3-8B with the prompt: Complete the sentence: The capital of France is.
The request selected two MLP coordinates: layer 13 neuron 7956 and layer 14 neuron 8949. It allowed four generated tokens and captured both coordinates through the prompt and continuation.
The retained result
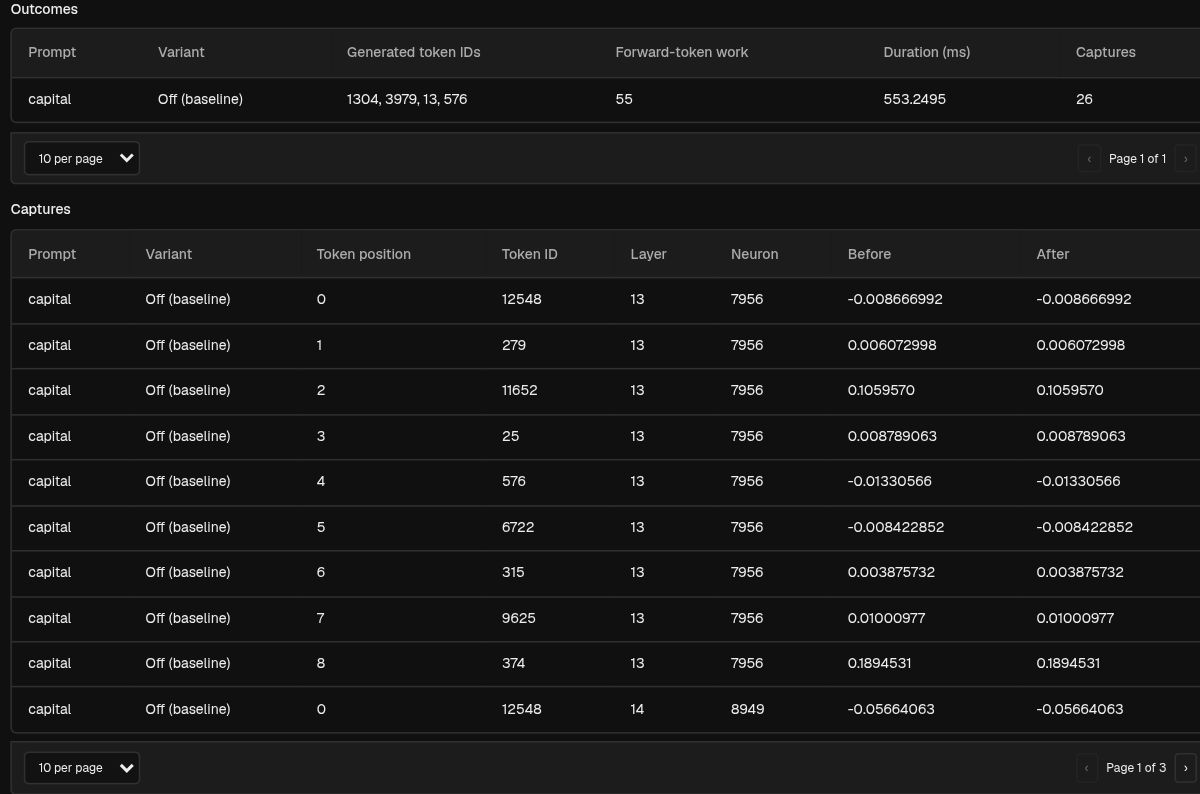
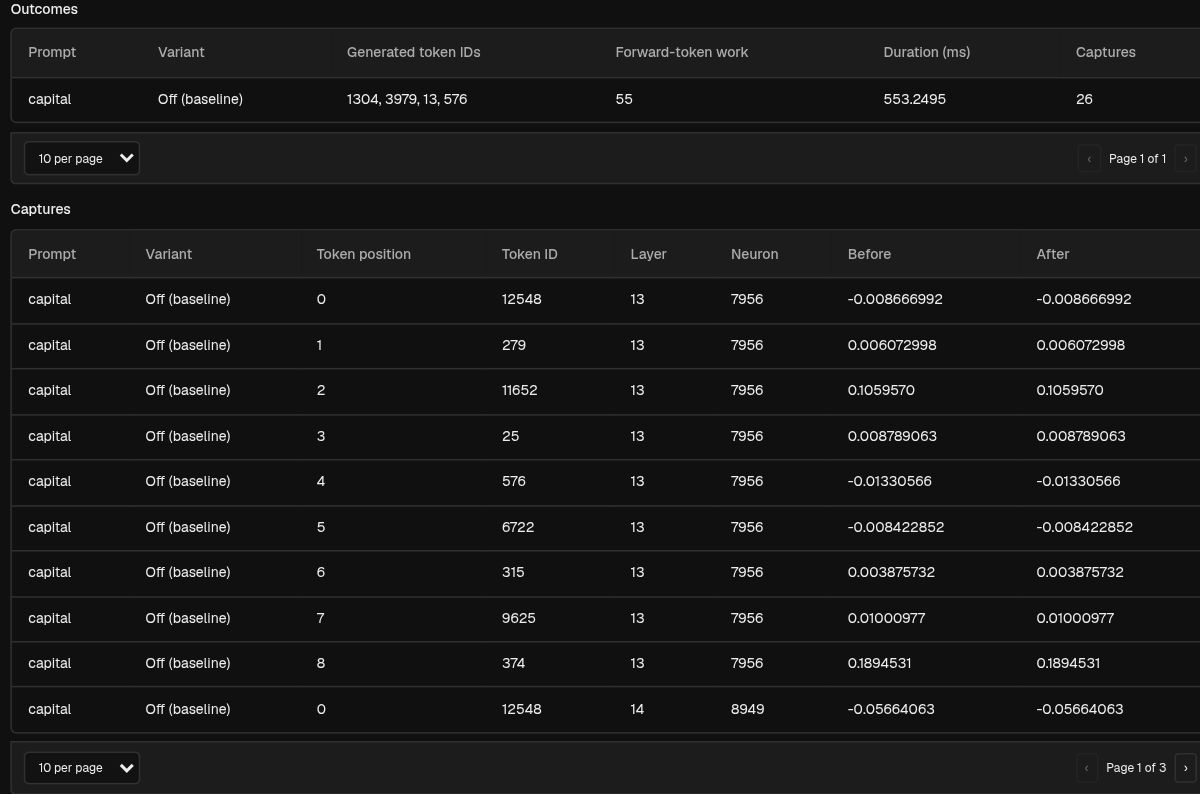
Actual outcome summary and the first 10 of 26 capture rows from one prompt and two coordinates. The 553 ms duration covers the CUDA outcome, excluding cold startup, model loading and the complete billable lifecycle. The capture rows are observations, not a quality score.
Open the full-size result image.
| Measurement | Observed result |
|---|---|
| Generated token IDs | 1304, 3979, 13, 576 |
| Capture records | 26 across two coordinates |
| Forward-token work | 55 |
| CUDA outcome duration | 553.2495 ms |
| Baseline before/after | Equal for all 26 captures |
All captured values were finite. For example, at token position 8 (token ID 374), layer 13 neuron 7956 recorded 0.189453125 before and after the read-only hook. Layer 14 neuron 8949 recorded −0.02197265625 at that same position. Their different values do not establish what either neuron means.
The retained result hash matched the native result, and the same token sequence and capture rows reopened in the web app. Decoding the retained token IDs requires the exact tokenizer. The observed usage charge was $0.502518 for this run; the short outcome duration does not describe its entire charged lifecycle.
This check establishes token-aligned activation capture. It provides no answer quality grade, weight update, saved model artifact or serving qualification. For the capture mechanism and verified CLI/SDK workflow, see the activation-inspection guide.